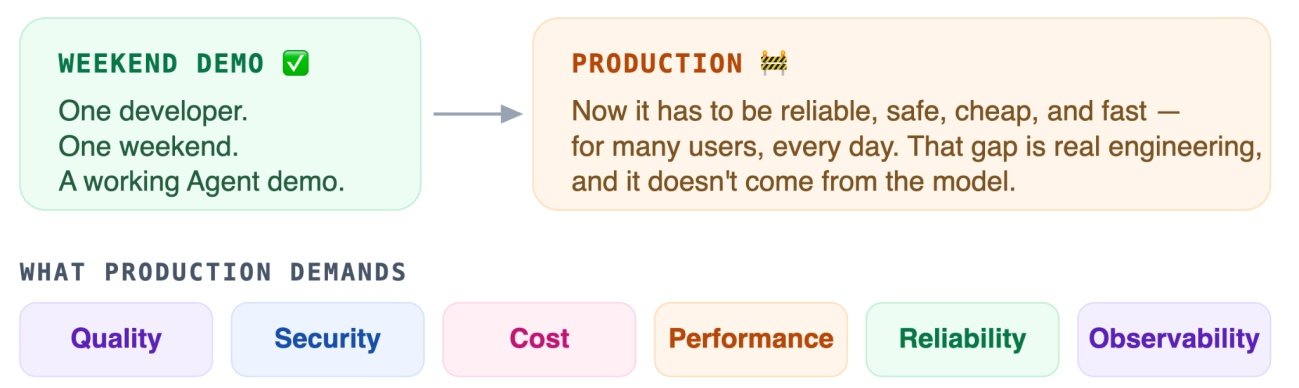
The transition from a functional artificial intelligence prototype to a production-grade autonomous agent represents one of the most significant engineering challenges in the current technology landscape. While spinning up a basic AI agent can often be achieved in an afternoon, building a system capable of operating reliably, securely, and cost-effectively at scale is a fundamentally different discipline. This evolution is defined by the construction of the "agent harness"—a structural and operational layer that surrounds the core model, providing the necessary stability that large language models (LLMs) lack on their own.
The Anatomy of the AI Agent Harness
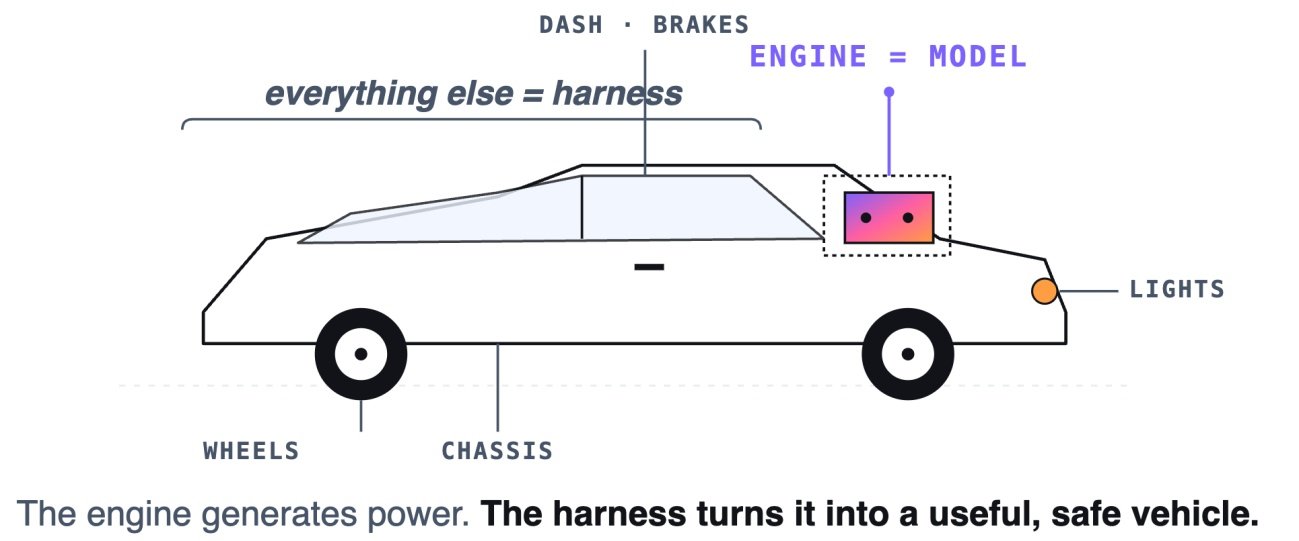
The concept of the agent harness, popularized in recent months, refers to the surrounding infrastructure that enables an agent to function as a reliable product rather than a mere experiment. If the LLM is the engine—providing the raw cognitive power—the harness is the vehicle chassis, braking system, and dashboard. It is what transforms a volatile, stateless model into a robust tool that can manage memory, execute external functions, enforce security guardrails, and provide visibility into system failures.
Industry analysts observe that as AI adoption matures, organizations are moving away from treating agents as singular, monolithic scripts. Instead, they are adopting a architectural approach that separates the model’s reasoning capabilities from the operational scaffolding. This shift allows developers to treat components such as retrieval-augmented generation (RAG), model routing, and cost management as deliberate design choices rather than reactive, one-off patches implemented after a system crash.
Chronology of the Shift: From Glue Code to Infrastructure
The trajectory of agent development has unfolded rapidly over the past two years:
- 2023 (The Experimental Phase): Developers focused on "prompt engineering" and basic orchestration using nascent frameworks. Reliability was secondary, and most production incidents were resolved by manual intervention or "hot-fixing" prompts.
- Early 2024 (The Tooling Emergence): As agents were deployed in professional settings, the fragility of these systems became apparent. The necessity for retries, logging, and consistent tool access led to the first iterations of custom-built, internal harness layers.
- Late 2024–Present (The Standardization Era): The industry has begun to formalize the "agent harness" as a distinct architectural requirement. Companies are now choosing between managed services (Harness-as-a-Service) and self-managed stacks (Infrastructure-as-Code) to stabilize their AI workflows.
Development vs. Operations: The Two Pillars
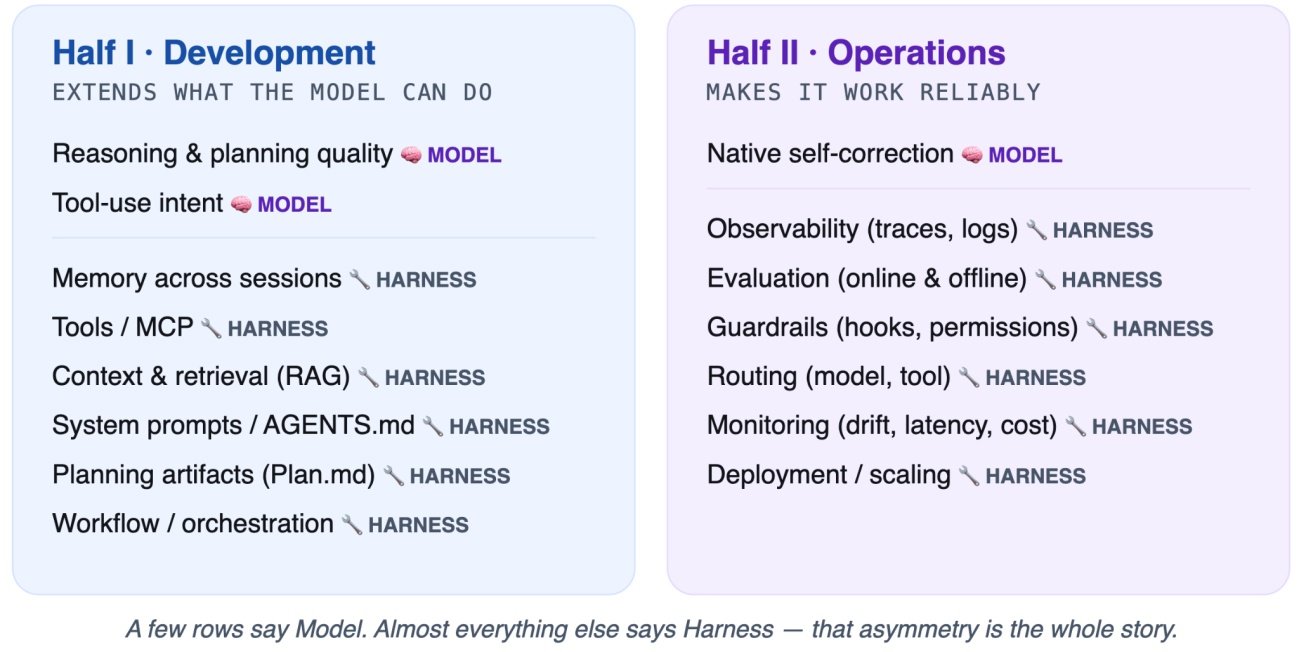
The agent harness is logically divided into two distinct halves: development and operations. The development half focuses on extending the model’s capabilities. This includes managing long-term memory across multiple user sessions, integrating tools via protocols like the Model Context Protocol (MCP), and fine-tuning prompt orchestration.
Conversely, the operations half mirrors the traditional DevOps lifecycle. It encompasses observability, automated evaluation of agent performance, the enforcement of guardrails to prevent harmful output, and real-time monitoring of token consumption and system drift. Failure to adequately invest in the operational side of the harness is the most common reason why AI projects fail to reach production readiness. Industry data suggests that agents without robust observability layers experience a 40% higher rate of "black box" failures, where developers cannot determine whether an error originated from a model hallucination, a tool execution failure, or a prompt misconfiguration.
Choosing the Path: HaaS vs. Self-Managed
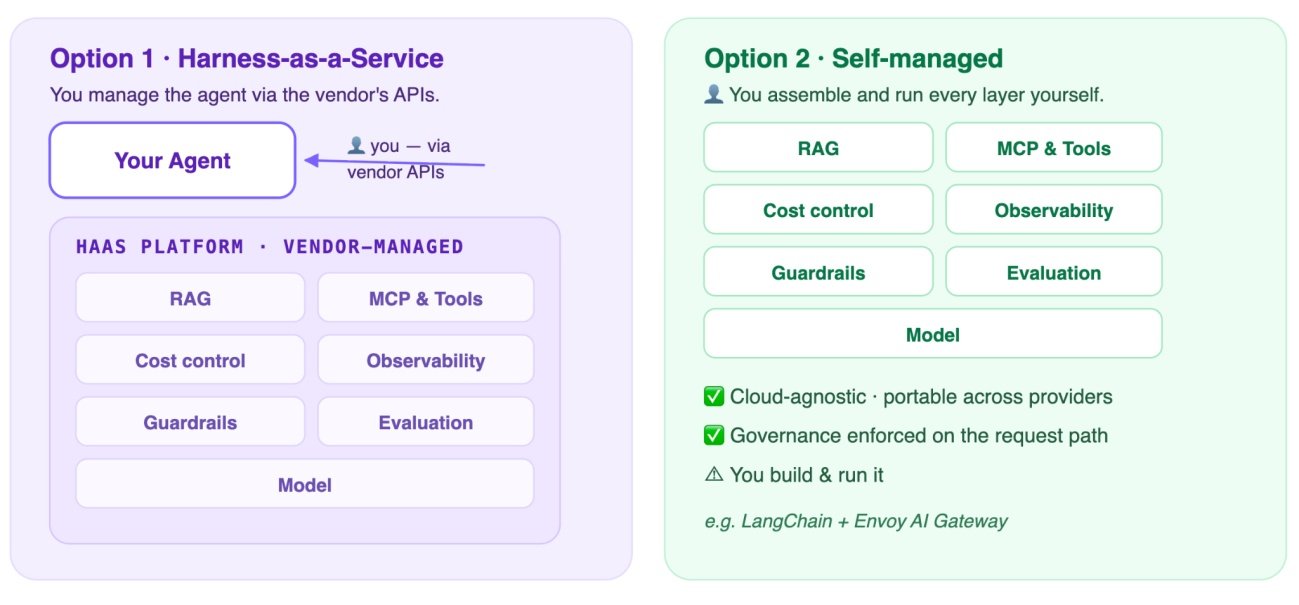
Organizations currently face a strategic decision regarding their stack: should they adopt a "Harness-as-a-Service" (HaaS) model or build a "self-managed" stack?
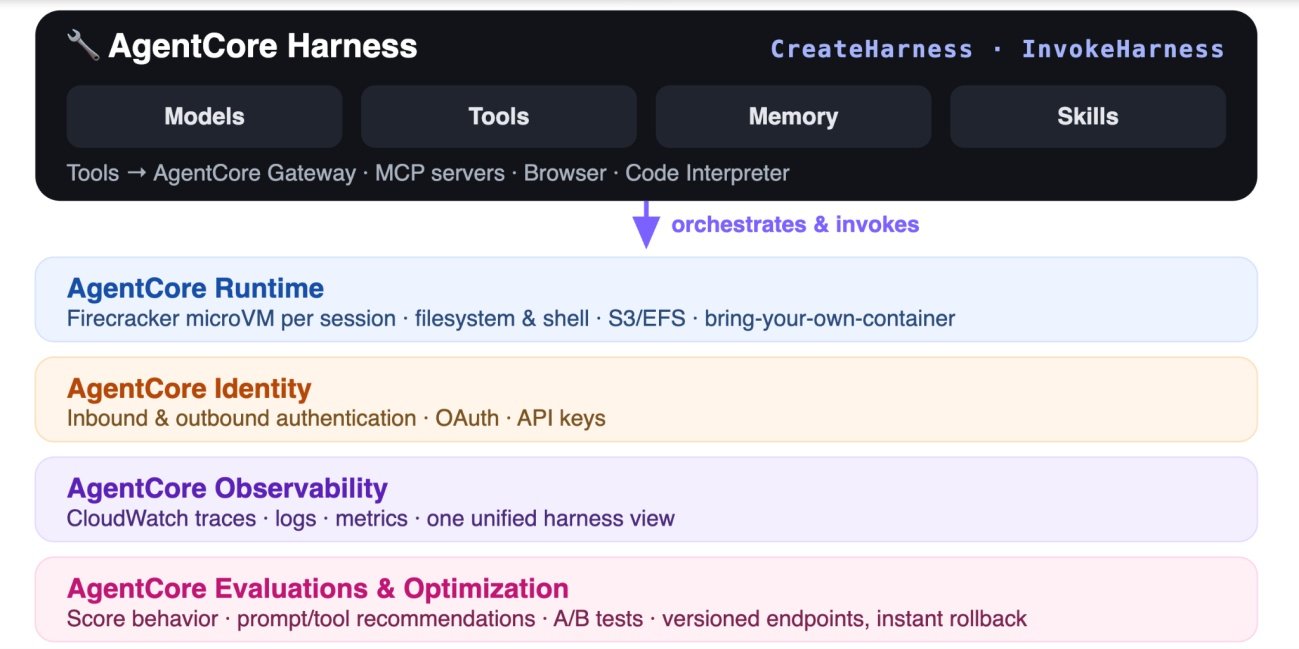
HaaS solutions, such as Amazon Bedrock AgentCore, Google Vertex AI Agent Engine, or the LangGraph Platform, provide managed APIs that handle the heavy lifting of the harness. These services offer pre-configured primitives for identity, runtime, and monitoring. The primary benefit is speed to market; by outsourcing the infrastructure, companies can focus their engineering resources on business logic and prompt design. However, this creates a degree of vendor lock-in, as the agent’s lifecycle becomes tied to the provider’s runtime environment.
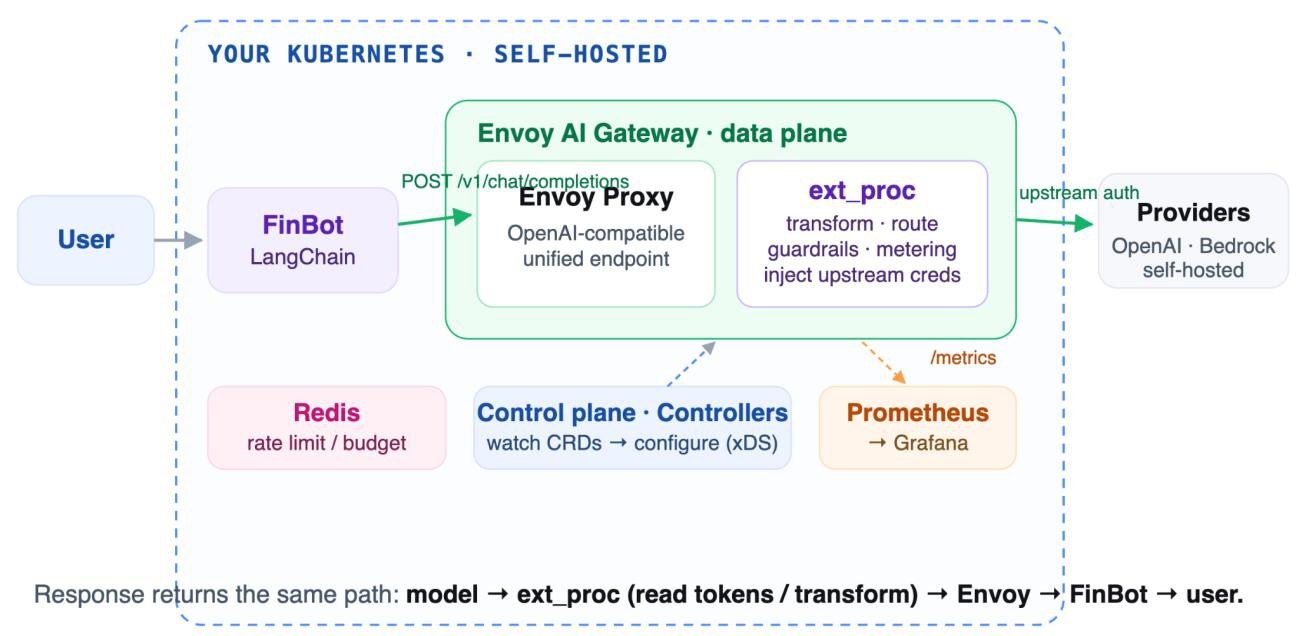
Alternatively, self-managed stacks—often built on tools like LangChain, LlamaIndex, or Envoy AI Gateway—offer maximum flexibility and control. This approach is favored by organizations requiring cloud-agnostic deployments or those with stringent compliance requirements that prevent the use of managed black-box services. While this provides total sovereignty over the stack, it shifts the burden of maintenance, scaling, and on-call rotations to the internal engineering team.
Fact-Based Analysis of Operational Implications
When assessing production readiness, three capabilities remain paramount: model access, cost control, and observability.
- Unified Model Access: A production-grade harness must act as a "front door" for the application. By abstracting the model provider, teams can swap between models (e.g., migrating from Claude to GPT-4o) or implement failover strategies via simple configuration changes rather than refactoring code.
- Cost Control: Autonomous agents are prone to "runaway loops," where an agent enters a recursive cycle of tool calls, potentially leading to catastrophic financial costs. Effective harnesses enforce hard caps on token usage, iteration counts, and time-outs, ensuring that budget constraints are enforced at the infrastructure level.
- Observability: In a multi-model environment, tracing a request through the system is notoriously difficult. Standardizing on OpenTelemetry (OTel) allows teams to maintain a consistent vocabulary for spans, enabling them to visualize the entire prompt-to-tool-to-response chain. Modern tools allow developers to set metrics for "Time to First Token" and inter-token latency, providing the data necessary to debug performance bottlenecks before they affect the end-user.
The Case Study of FinBot
Consider "FinBot," an agent designed to summarize quarterly financial filings. In a demo environment, this agent might simply call an LLM and a local document store. In a production harness, however, FinBot must handle authenticated access to an MCP server for secure document retrieval, execute code in a sandboxed environment to calculate financial metrics, and maintain a persistent thread ID in a database to ensure memory across turns.
Whether implemented via a managed API or a self-managed Kubernetes cluster, the underlying complexity remains constant. The difference lies only in where the "pager" goes when the system breaks. In the HaaS model, the vendor manages the underlying runtime, while in the self-managed model, the team is responsible for the health of the containerized services and the persistent state of the database.
Broader Impact and Future Outlook
The rise of the agent harness signifies the professionalization of the AI industry. As businesses move past the hype cycle, the focus is shifting toward "boring" engineering: reliability, auditability, and operational stability.
Industry experts suggest that as these patterns become standardized, we will likely see a convergence of the two models. Managed services will likely offer more "escape hatches" that allow developers to inject custom code into the runtime, while self-managed stacks will adopt more standardized "off-the-shelf" components to reduce the burden of custom maintenance.
Ultimately, an AI agent is a product, not a model. The success of any agentic implementation is predicated on the quality of the harness. By treating the operational environment as a first-class citizen—just as software engineers have done with web services for decades—teams can build agents that move beyond the limitations of prototypes and deliver actual value in production environments. The core reasoning power of the model is the catalyst, but the harness is the container that ensures that power is used safely and predictably.